Best Rack Mount Static Var Generator Factory: Key Factors to Consider
2026-10-04
A single voltage sag can idle an entire production line—yet many facilities still treat reactive power compensation as an afterthought. If you're sourcing a rack mount static var generator, the factory behind the product matters as much as the specs on paper. Build quality, real-world testing, and responsive engineering support separate a dependable partner from a costly gamble. In this guide, we'll walk through the key factors to weigh before committing—and why GEYA consistently earns a place on shortlists when reliability can't be compromised.
Factory Floor Signals That Predict Long-Term Reliability
Walking a manufacturing line reveals more about a machine's future than any spec sheet. Operators who listen closely to the rhythm of a press, notice slight temperature shifts on a motor housing, or spot recurring minor jams on a conveyor are reading early warnings. These floor-level observations often surface months before a failure shows up in vibration data or oil analysis reports. The real predictors are rarely dramatic—they hide in the subtle changes that only experienced eyes and ears catch during routine rounds.
Take the case of a packaging plant where a labeler began dropping one bottle in every few hundred. No alarm triggered, and throughput stayed within tolerance. But a line technician traced the issue to a worn cam follower that was gradually changing the timing. Replacing that $40 part during a planned shift avoided what would have become a catastrophic jam two weeks later. Such stories repeat across industries: a slight increase in air leakage from a pneumatic fitting, a new harmonic whine from a gearbox, or a hydraulic hose that feels stiffer than it did last month. These are not anomalies—they are the floor speaking in a language of wear, misalignment, and fatigue.
What separates reliable operations from those that lurch from breakdown to breakdown is not a sophisticated software dashboard. It is a disciplined habit of recording these small deviations and acting on them early. Some plants use simple logbooks or shift-handover notes to capture what seems trivial. Over time, patterns emerge: a specific conveyor section that needs belt tension adjustments every six weeks, a cooling fan that draws slightly higher current before bearings degrade. By treating the factory floor as a living diagnostic surface, teams can predict long-term reliability without waiting for sensors to scream. The most valuable signal is often the one that never appears on a screen—and that is exactly why it matters.
Why Component Provenance Matters More Than You Think
Every chip on a board carries a story that most engineers never bother to read. That story begins long before the part lands in your BOM—in a fab cleanroom, a test floor, or a broker's shelf. When you skip tracing that history, you're not just accepting a part; you're inheriting every hand it passed through, every re-marking it endured, and every spec it may have quietly lost along the way.
Consider what actually breaks when provenance is murky. A counterfeit regulator might pass a quick bench test, then drift under thermal load because its silicon was pulled from a scrapped reel. A re-balled FPGA could work fine in the lab, yet fail after three months of thermal cycling because the substitute substrate wasn't rated for your profile. These failures don't announce themselves as counterfeit—they look like design flaws, manufacturing defects, or bad luck. That's the real cost: your team chases ghosts while the true culprit sits in a gray-market invoice.
The teams that take provenance seriously don't just add a column to a spreadsheet. They treat component history as an input to reliability math. They know a part that sat in uncontrolled humidity for two years isn't the same as one that shipped from the factory last month, even if the markings match under a microscope. Once you've seen a field return traced back to a washed part with a fake date code, you stop treating provenance as paperwork and start treating it as survival data.
Testing Rituals That Separate Serious Builders From the Rest
Most builders write tests after the code is finished. The serious ones start by writing a failing test that names the exact behavior they want. They don't just check that the function returns true; they check the edge case that broke production last Tuesday. Then they watch it fail for the right reason, not because of a typo or missing import. That pause before making it pass is the whole point.
Another ritual is actively trying to break the system. They turn off a database, kill a background worker, or add 300 milliseconds of latency to a third-party call. Then they run the suite and note which tests still pass but shouldn't, or which fail without a clear message. Flaky tests get quarantined and fixed the same day, not left to rot in a skipped folder.
After a failure, they don't just patch the line and move on. They write a tiny post-mortem in the commit message: what the test missed, why the signal wasn't caught, and what new test would have caught it. That new test gets added before the fix. Over time, their test suite starts to read like a list of past disasters, each one converted into a guardrail.
Custom Fit, Not Cut and Paste: Real SVG Personalization
Most SVG customization tools just swap a name or hex code inside a fixed template. That works for badges, but it falls apart when a user wants a different silhouette, a tighter stroke, or a layered composition that actually responds to their input. Real personalization means every path, curve, and anchor point can adapt—not just the text field.
Think about a monogram where the initials don't just sit on top of a shield but reshape the shield’s contour to balance the letterforms. Or a landscape scene where changing one color value shifts the gradient stops across the whole sky, not just a single rectangle. That requires SVG built with variables in mind, not flattened artwork imported from a design file.
The payoff is subtle but obvious to users: the result feels made for them, not stamped with their name. Instead of offering ten static variants, you give them knobs that change geometry, stroke weight, negative space, and rhythm. The SVG stays light, the output stays crisp at any size, and the personalization actually changes the structure—not just the surface.
The Real Cost of a Bargain Rack Mount SVG
You spot a rack mount SVG listed at a price that seems too good to ignore. The specs look decent, the seller has a few positive reviews, and your budget breathes a sigh of relief. But once it arrives, the real cost begins to surface. Mounting holes that don't align with standard rails, a chassis that flexes under the weight of your other gear, and a power supply that whines louder than a server fan at full tilt. You tell yourself you'll make it work, but every adjustment eats into time you can't get back.
Then there's the software side. A bargain unit often ships with firmware that hasn't seen an update in years, leaving you to chase down obscure driver packages or settle for reduced functionality. The initial savings evaporate when you factor in the hours spent troubleshooting, the replacement parts you buy to fix what should have worked out of the box, and the downtime that happens when the unit finally gives up. Reliability isn't a feature you can bolt on later.
Worse still, you may discover the bargain unit was never designed for sustained loads or proper thermal management. It runs hot, draws more power than it should, and one day it takes something else down with it. By the time you replace it with a model that costs twice as much, you've already spent the difference three times over. Sometimes the cheapest option is the most expensive lesson you'll ever buy.
After the Invoice: Support That Keeps Your Grid Running
Most vendors vanish once the payment clears. We take the opposite route. From the moment your system goes live, a dedicated engineer—not a rotating call center—owns your account. That person knows your site layout, your load profile, and the quirks of your local utility. When you call at 2 a.m. because a breaker tripped, you get someone who can pull up your schematics before the second ring.
Our support isn't limited to emergency response. Every quarter, we review your energy storage logs and inverter telemetry to spot drift before it becomes downtime. Firmware updates are scheduled around your peak shaving windows, never during them. If a component underperforms, we ship a replacement before you ask—because our monitoring flags it first. That's the difference between a supplier and a partner who keeps your grid running.
What does this look like in practice? A manufacturing plant in Ohio avoided a three-day outage because our remote diagnostics caught a failing capacitor bank on a Tuesday, and the replacement part arrived Friday. No extra charge, no finger-pointing. Just a system that stayed online. That's the support after the invoice: proactive, personal, and relentlessly focused on uptime.
FAQ
The difference usually shows up in how they handle thermal design and component derating. A dependable factory will share specific test data for continuous operation at full load, not just a glossy datasheet. Ask about their failure rate over the first two years and how they isolate faulty modules in the rack.
In-house testing is a strong signal because it shortens feedback loops during production. Look for facilities that can simulate grid disturbances and load swings rather than only performing basic insulation checks. If they can provide recorded waveforms from their burn-in tests, that is even better.
It often matters more than price. Rack dimensions, communication protocols, and reactive power response curves vary by site. A factory that treats customization as a core service, not an afterthought, will ask about your specific harmonic environment and control system before quoting.
Focus on the long-term availability of key parts like IGBT modules, capacitors, and control boards. A factory that relies on obscure or end-of-life components may leave you stranded for repairs. Request a list of approved component vendors and confirm they have multiple supply channels.
Rack mount units often run in mission-critical installations, so downtime is expensive. Strong after-sales support means remote diagnostics, readily available spare modules, and clear escalation paths. Test their responsiveness during the evaluation stage—how quickly they answer technical questions often mirrors their post-sale behavior.
At minimum, expect safety certifications like CE or UL for the complete rack assembly, not just individual components. For grid-connected operation, compliance with local utility standards such as IEEE 519 or EN 61000 is also relevant. Verify that the certificates are current and cover the exact models you plan to buy.
Look at their production history, facility ownership, and whether they have a stable engineering team. A factory that has recently shifted ownership or relies on short-term contractors may struggle with consistent quality. Visiting the production floor, even virtually, can reveal how organized their processes are.
R&D investment determines whether the product will keep up with grid code changes and new communication standards. Ask about recent firmware updates and how they handle field-reported issues. If the factory releases regular technical bulletins or offers upgrade paths, that is a sign they will not abandon the product line.
Conclusion
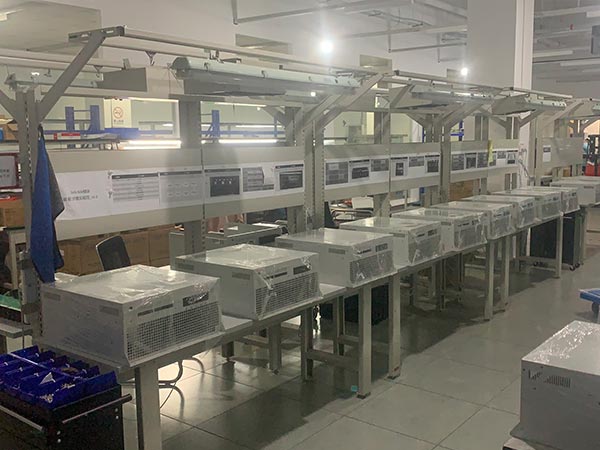
Walk the production floor of any rack mount static var generator factory and the signs of long-term reliability are often visible before a single unit is shipped. Pay attention to how subassemblies are handled, whether torque tools are calibrated on a regular rhythm, and how failures from earlier batches get traced back to their source. Component provenance is one of those quiet factors that separates a factory that will still be answering calls in a decade from one that disappears after the warranty period. Builders who can name the exact foundry for their IGBT modules and the winding house for their reactors tend to make different choices during shortages and price spikes. Add to that a testing ritual that goes beyond a basic power-on check—thermal cycling under load, harmonic injection at multiple points, and full-voltage insulation tests—and you start to see why serious manufacturers treat every unit as a small engineering project rather than a commodity.
Customization matters because a reactive power compensation scheme that works in a data centre will not necessarily hold up in a steel mill or a solar farm with rapid cloud transients. A real SVG builder asks about the harmonic profile, the existing capacitor banks, the communication protocol, and the physical space constraints before quoting a part number. If the answer is a ready-made spec sheet with no questions asked, the bargain price often hides skipped steps: thinner copper, fewer filter stages, or firmware that locks you out of advanced tuning. After the invoice, the difference becomes even starker—remote diagnostics, local spare part stock, and engineers who understand your grid code rather than reading from a script keep the system online during a voltage dip. The real cost of a bargain rack mount SVG is measured in downtime, derating, and repeated service visits, not the initial purchase order.
Contact Us
Contact Person: Leo
Email: [email protected]
Tel/WhatsApp: +86-13567770207
Website: https://www.geyapower.com/